

 “He knows if you’ve been bad or good…”
As kids, we accepted the magic. As engineers in 2025, we need to understand the mechanism. So let’s imagine Santa’s “naughty or nice” system as a modern AI architecture running at scale. What would it take to make it observable when things go wrong?
The architecture: Santa’s distributed AI system
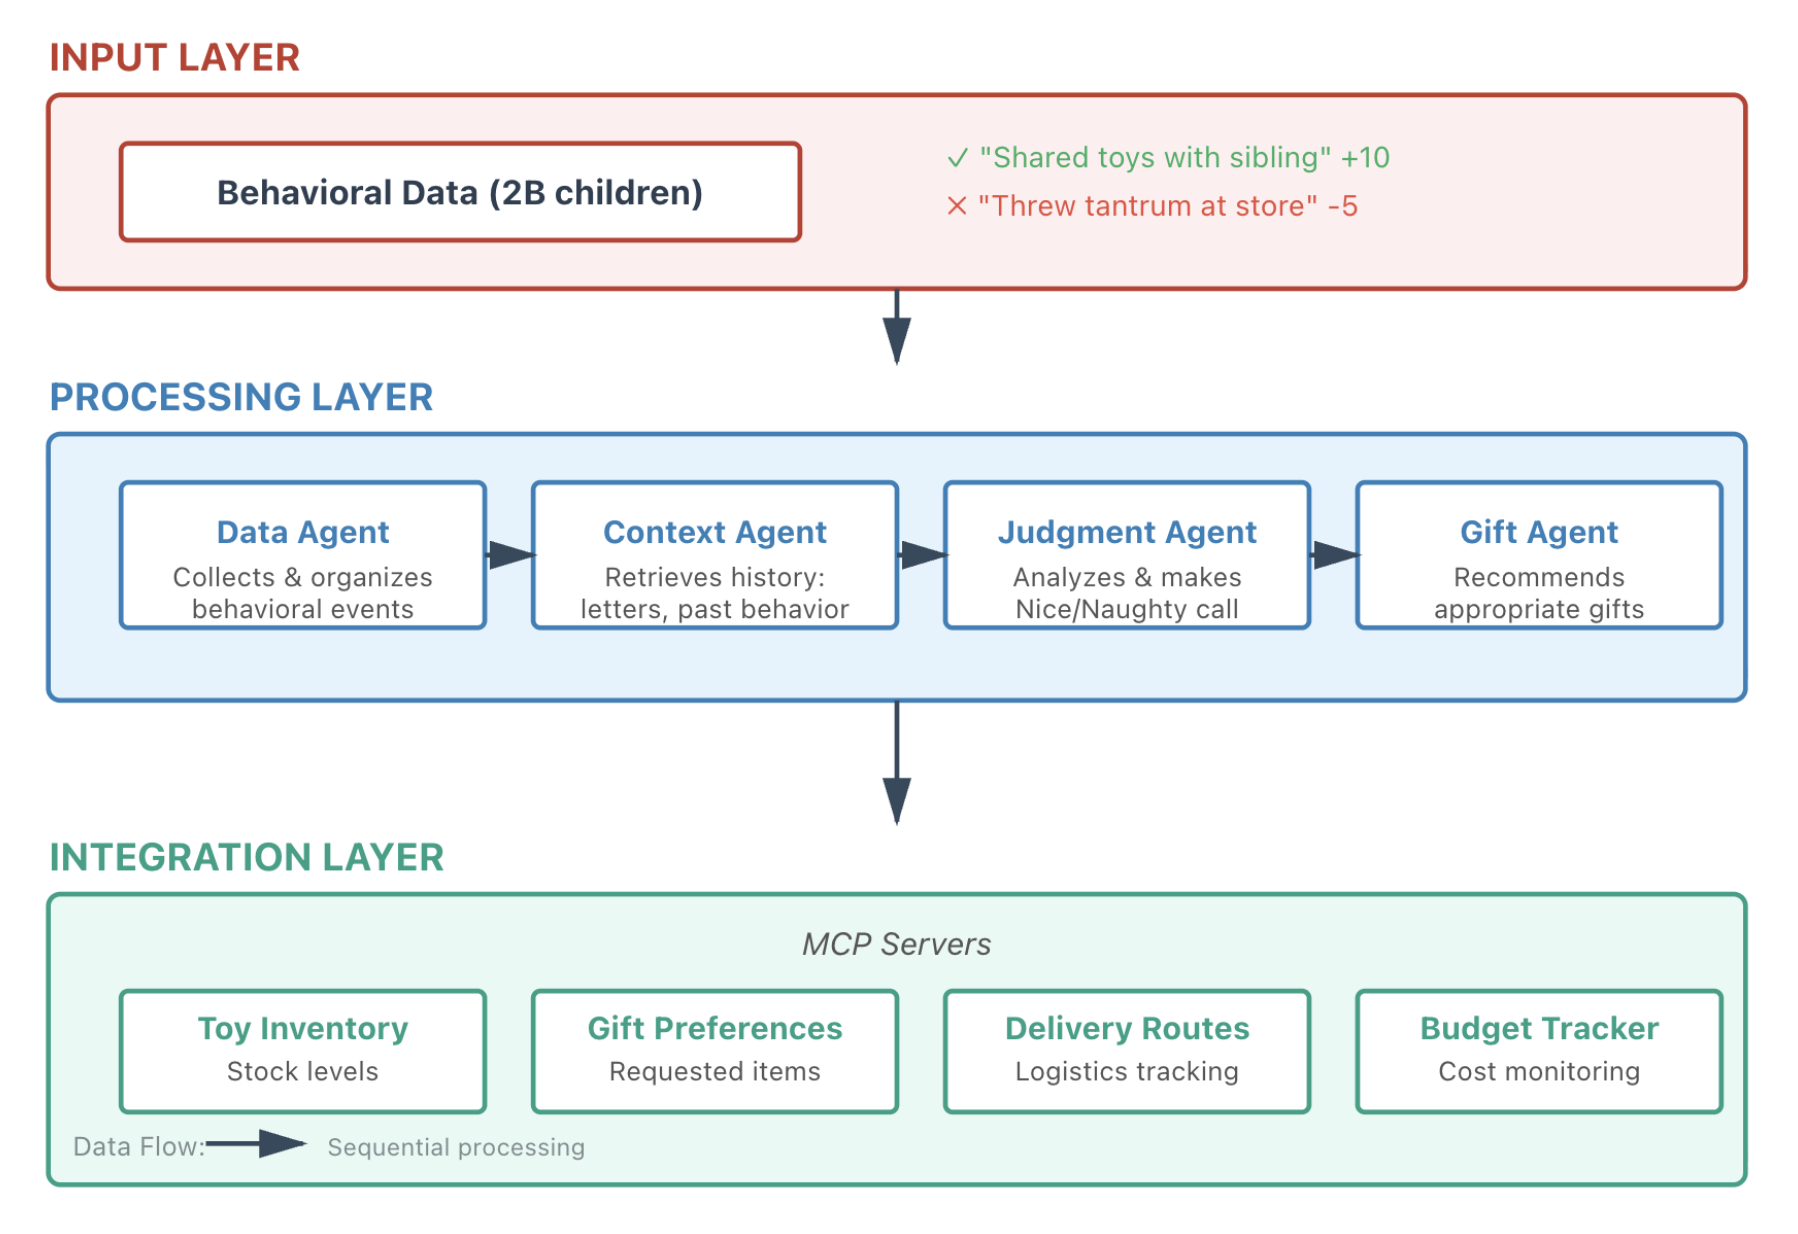
The three layers of 'Santa's distributed AI system architecture
The Problem: A good child on the Naughty List
It’s Christmas Eve at 11:47 PM. A parent calls, furious. Emma, age 7, has been a model child all year. She should be getting the bicycle she asked for. Instead, the system says: Naughty List - No Gift. You pull up the logs:Why AI Systems are hard to debug
Black box reasoning and reproducibility go hand in hand. With traditional debugging, you step through the code and find the exact line that caused the problem. With AI agents, you only see inputs and outputs. The agent received three timeouts and decided to default to NAUGHTY_LIST. Why? Neural network reasoning you can’t inspect. And even if you could inspect it, you couldn’t reliably reproduce it. Run Emma’s case in test four times and you might get:- Refused to eat vegetables (10 times) but helped put away dishes
- Yelled at siblings (3 times) but defended a classmate from a bully
- Skipped homework (5 times) but cared for a sick puppy
What Santa Actually Needs
The answer isn’t to throw out traditional observability, but to build on top of it. Think of it as three layers. This is exactly what we’ve built at LaunchDarkly. Our platform combines AI observability, online evaluations, and feature management to help you understand, measure, and control AI agent behavior in production. Let’s walk through how each layer works. Start with the fundamentals. You still need distributed tracing across your agent network, latency breakdowns showing where time is spent, token usage per request, cost attribution by agent, and tool call success rates for your MCP servers. When the Toy Inventory MCP goes down, you need to see it immediately. When costs spike, you need alerts. This isn’t optional. It’s table stakes for running any production system. For Santa’s workshop, this means tracing requests across Data Agent → Context Agent → Judgment Agent → Gift Agent, monitoring MCP server health, tracking token consumption per child evaluation, and alerting when costs spike unexpectedly. It’s important to note, LaunchDarkly’s AI observability captures all of this out of the box, providing full visibility into your agent’s infrastructure performance and resource consumption. Then add semantic observability. This is where AI diverges from traditional systems. You need to capture the reasoning, not just the results. For every decision, log the complete prompt, retrieved context, tool calls and their results, the agent’s reasoning chain, and confidence scores. When Emma lands on the Naughty List, you can replay the entire decision. The Gift Agent received three timeouts from the Toy Inventory MCP, interpreted “inventory uncertain” as “cannot fulfill request,” and defaulted to NAUGHTY_LIST as the “safe” outcome. Now you understand why it happened. And more importantly, you realize this isn’t a bug in your code. It’s a reasoning pattern the model developed. Reasoning patterns require different fixes than code bugs. LaunchDarkly’s trace viewer lets you inspect every step of the agent’s decision-making process, from the initial prompt to the final output, including all tool calls and the reasoning behind each step.
View and inspect traces in LaunchDarkly.